
I swear, it seems like just weeks ago that Twitter’s biggest Deepseek Stan teortaxes was sadly predicting American frontier models peeling ahead of Chinese open-source models until we reach the singularity. Mind you…he’s not on Team America. It was just a reflection of what everybody thought things were going. The lead in compute held by the American labs seemed insurmountable. And Anthropic’s Fable 5, thought to be so advanced it was at one point pulled from circulation so that non-Americans can’t get their grubby paws on it, seemed like a qualitative and quantitative leap forward.
It’s actually hard to find some of this stuff because I didn’t take screenshots and it’s hard to find old tweets. Just…trust me bro. Around the time when Fable 5 got pulled especially, it seemed like everyone was grimly bearish on Chinese lab’s ability to do more than follow at a longer and longer lag.
Still. Some wondered when the Chinese would catch up to Fable/Mythos:
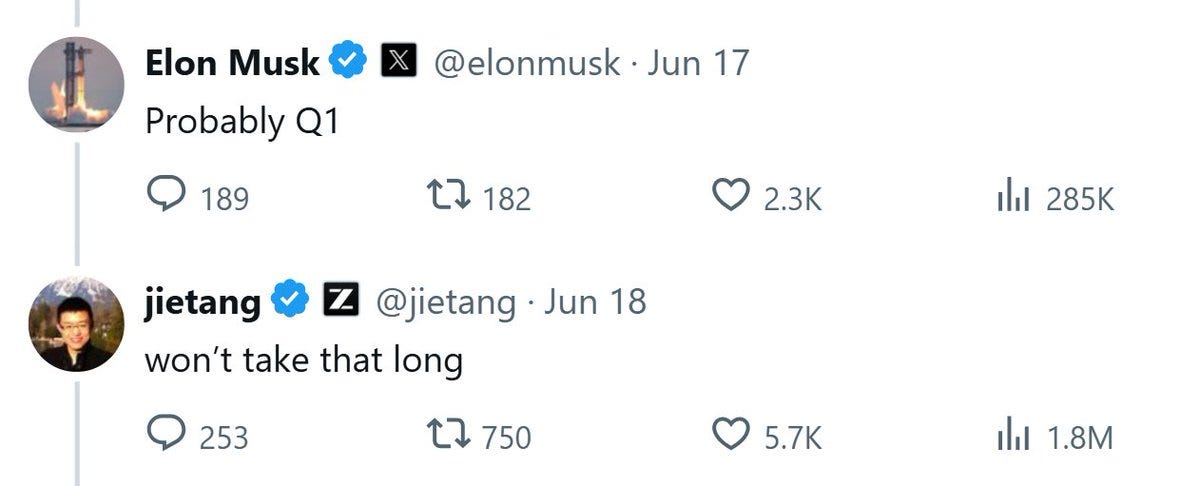
I assume you’re familiar with Elon. Jietang would be the lead scientist behind China’s Zuipu AI, which caused a mini-frisson with their capable GLM-5.2 model about a moth ago.
Today, Kimi 3 dropped and depending on the benchmarks, it topped some charts even in front of Fable 5.
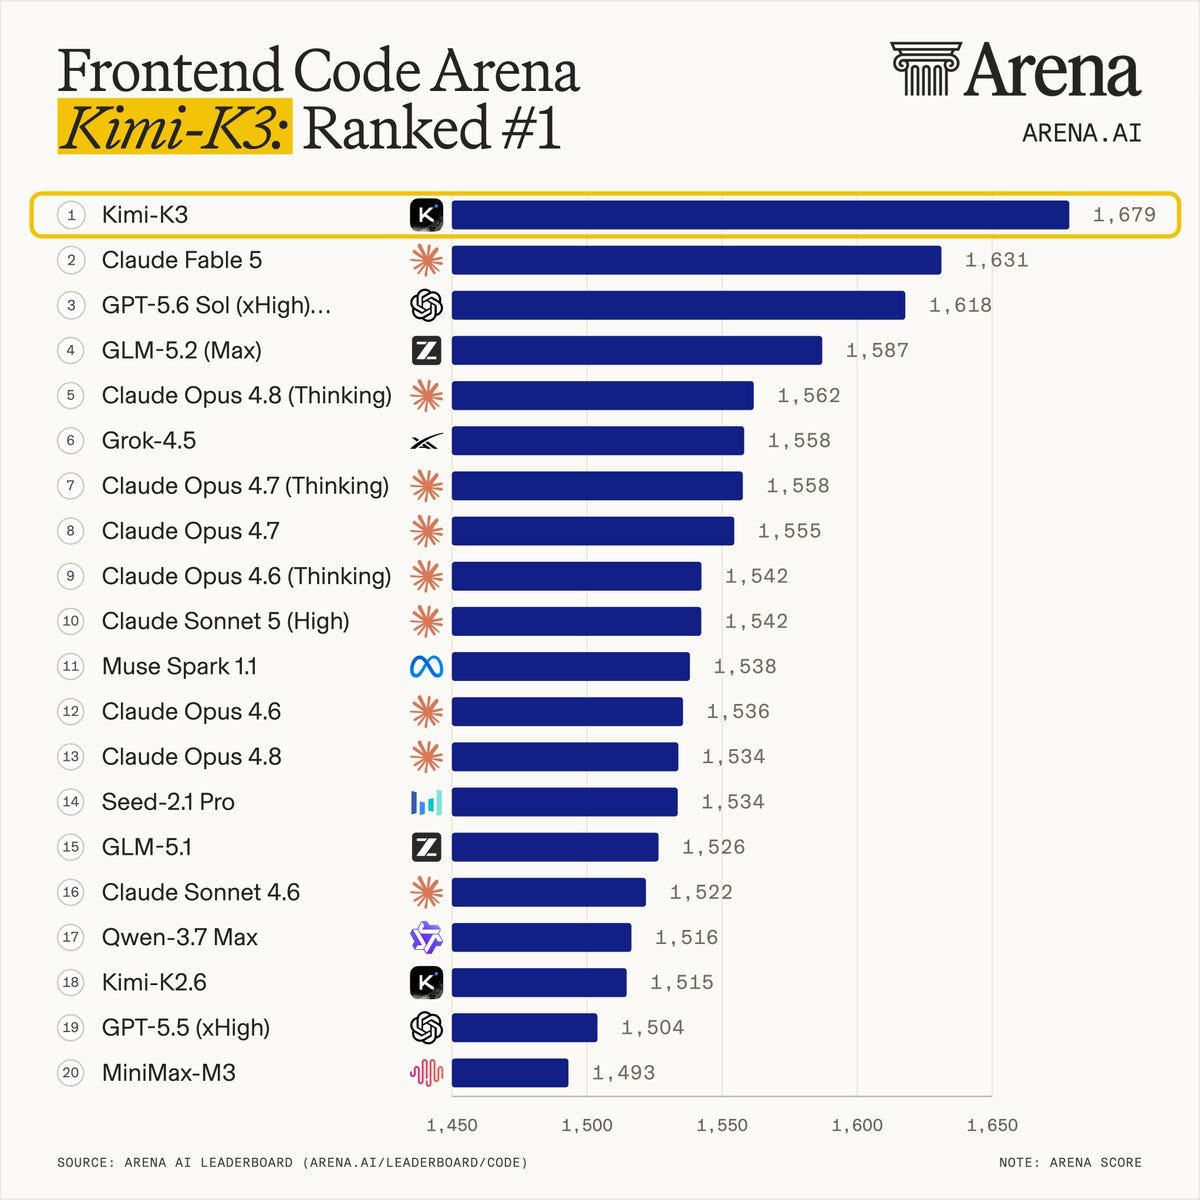
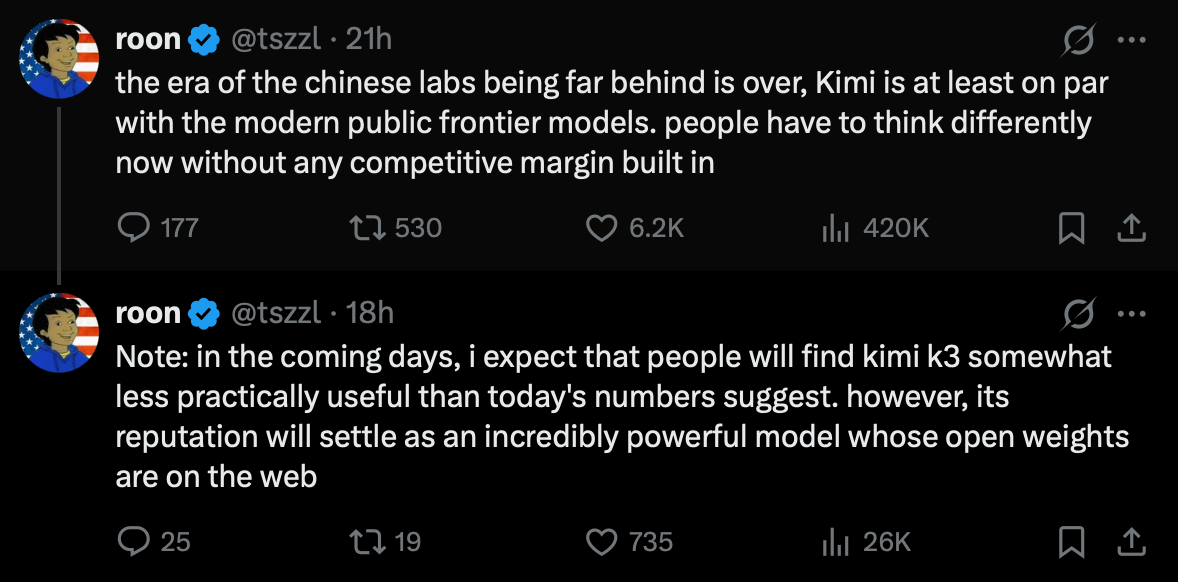
This should not have been possible. The conventional wisdom is that Chinese labs have only managed to fast-follow US models through the process of “distillation”, a method of reverse-engineering. But Kimi 3 didn’t just meet but BEAT top models including Anthropic’s Fable 5, a model so powerful it was briefly restricted from all non-US users by order of the US Government. While it is possible that US labs are still ahead with more powerful models kept under wraps, if they haven’t been released there would be no way for Moonshot to use distillation to build Kimi 3 up to state of the art.
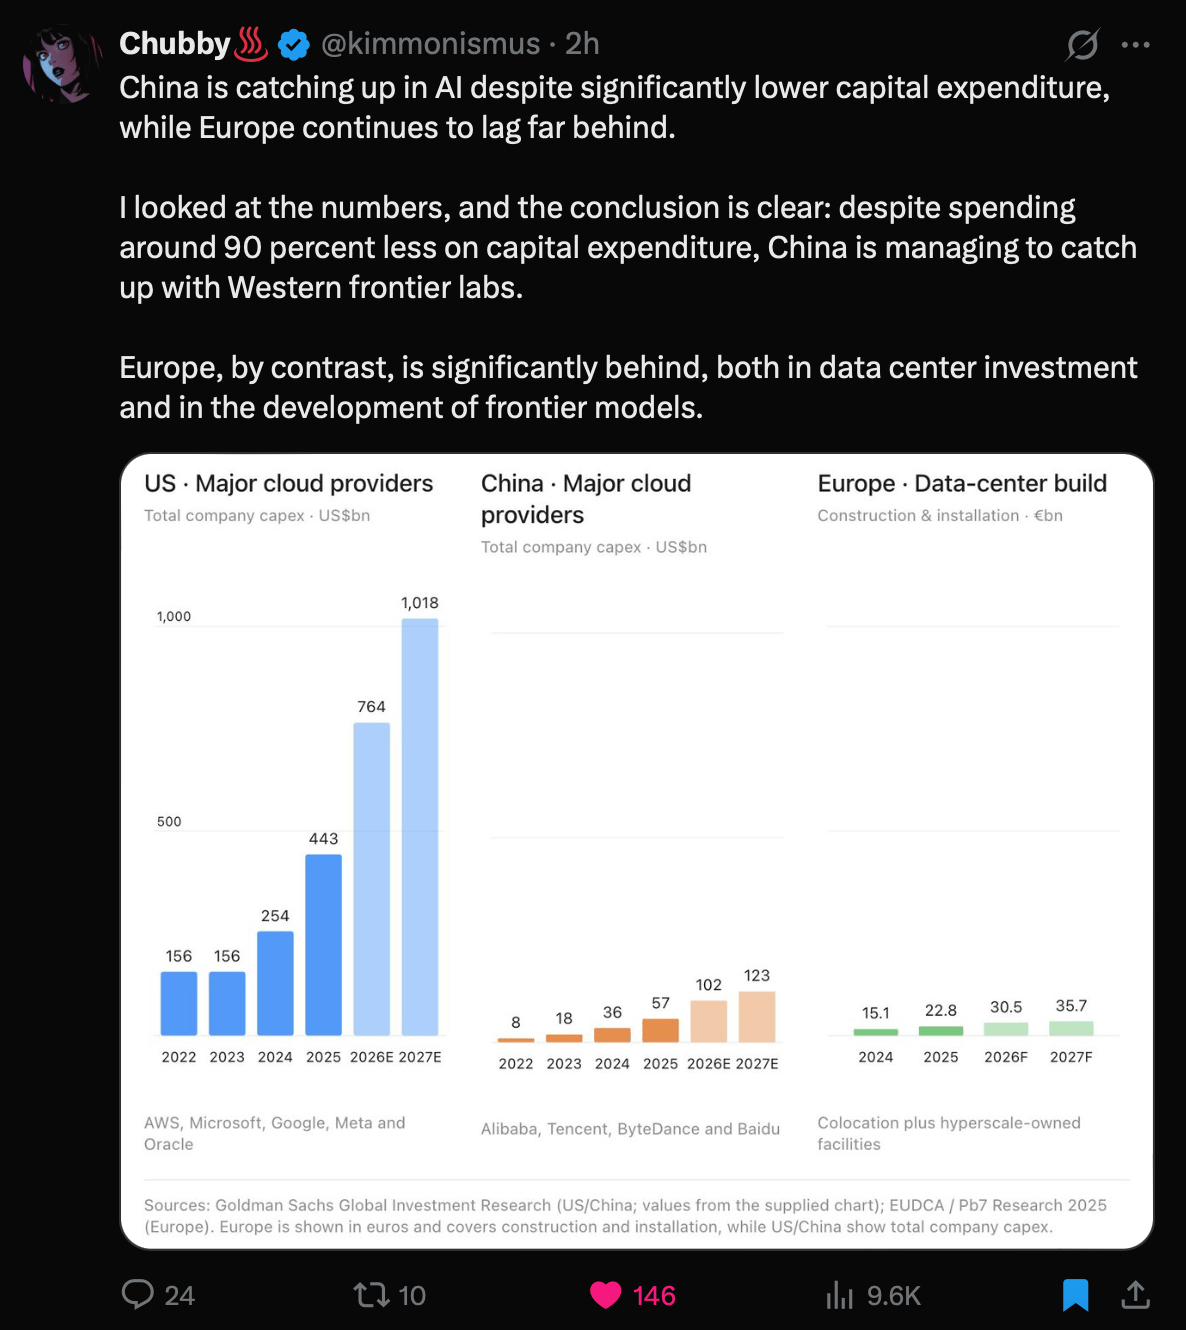
Ironically, despite a lot of self-serving scaremongering from the likes of Anthropic’s Dario Amodei that it would be a disaster for the world if autocratic China pulls ahead on AI, it’s arguable that the Chinese philosophy towards AI is a lot better for humanity.
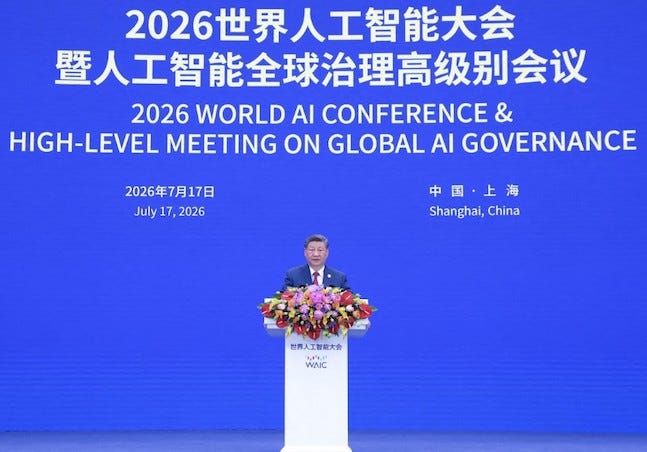
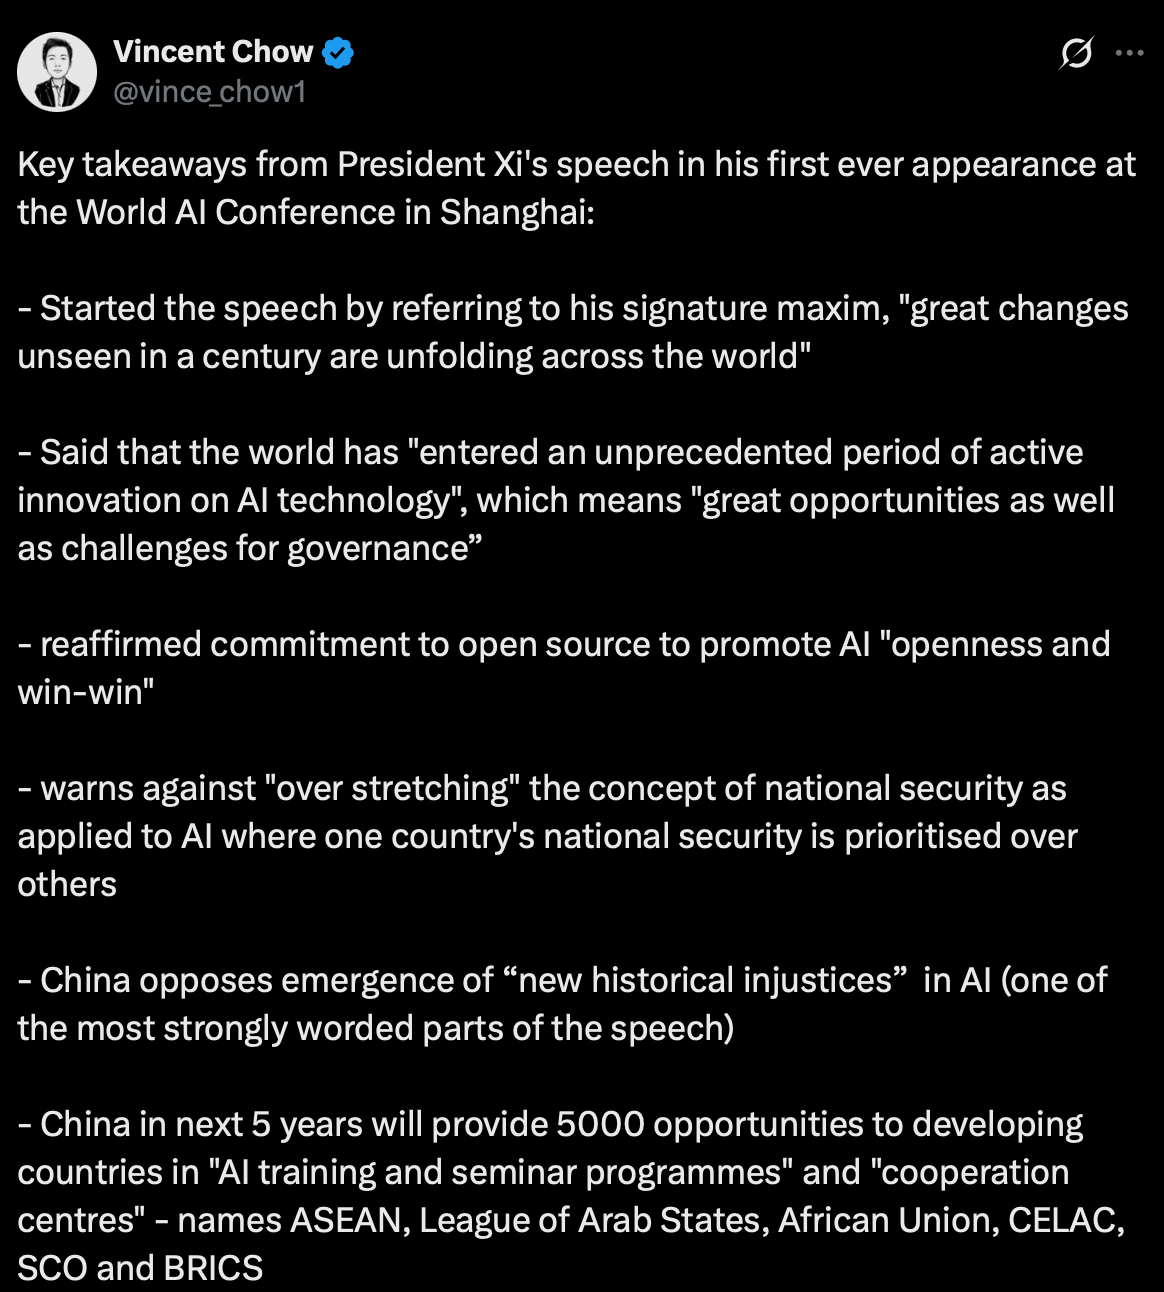
“AI is a shared crystallization of human wisdom and a precious asset belonging to all humanity. We must practice genuine multilateralism,” said Chinese President Xi Jinping at an AI conference in Shanghai today. He reiterated the Chinese commitment to open-source AI and to make sure that the best models will remain available to the global south. This stands in stark contrast to the Americans, who refused to even promise access to top-tier models to their allies.
I do not, dear reader, assume that anyone does anything good purely out of the grace of their intentions. But I do believe that values matter and when a global actor acts repeatedly in line with those values, it’s ok to extend some trust. At this point, I certainly trust the Chinese with AI over American techbros. At least, it is well to have another option.
There are still opportunities for China to disappoint us all, but for now, their commitment to open source is holding!
Anthropic’s brief withholding of Mythos was a PR stunt to drive up funding (along with cozying up with the Pope), and in general to keep the “mythos” of an inevitable AI doom.
One useful distinction here is between winning a benchmark and winning deployment. The signal I’m seeing is not only that Chinese labs are narrowing the capability gap, but that open weights, lower inference costs, and faster product iteration are turning “good enough” models into the default choice for real workloads. That feedback loop may matter more than any single leaderboard result. I’d be curious to see Kimi 3 compared on 30-day production workloads—agent reliability, tool use, and cost per completed task—not just benchmark snapshots.